Metrics Delivery to Slack and Email Without a Dashboard
Define each metric once, then push it to Slack and email.
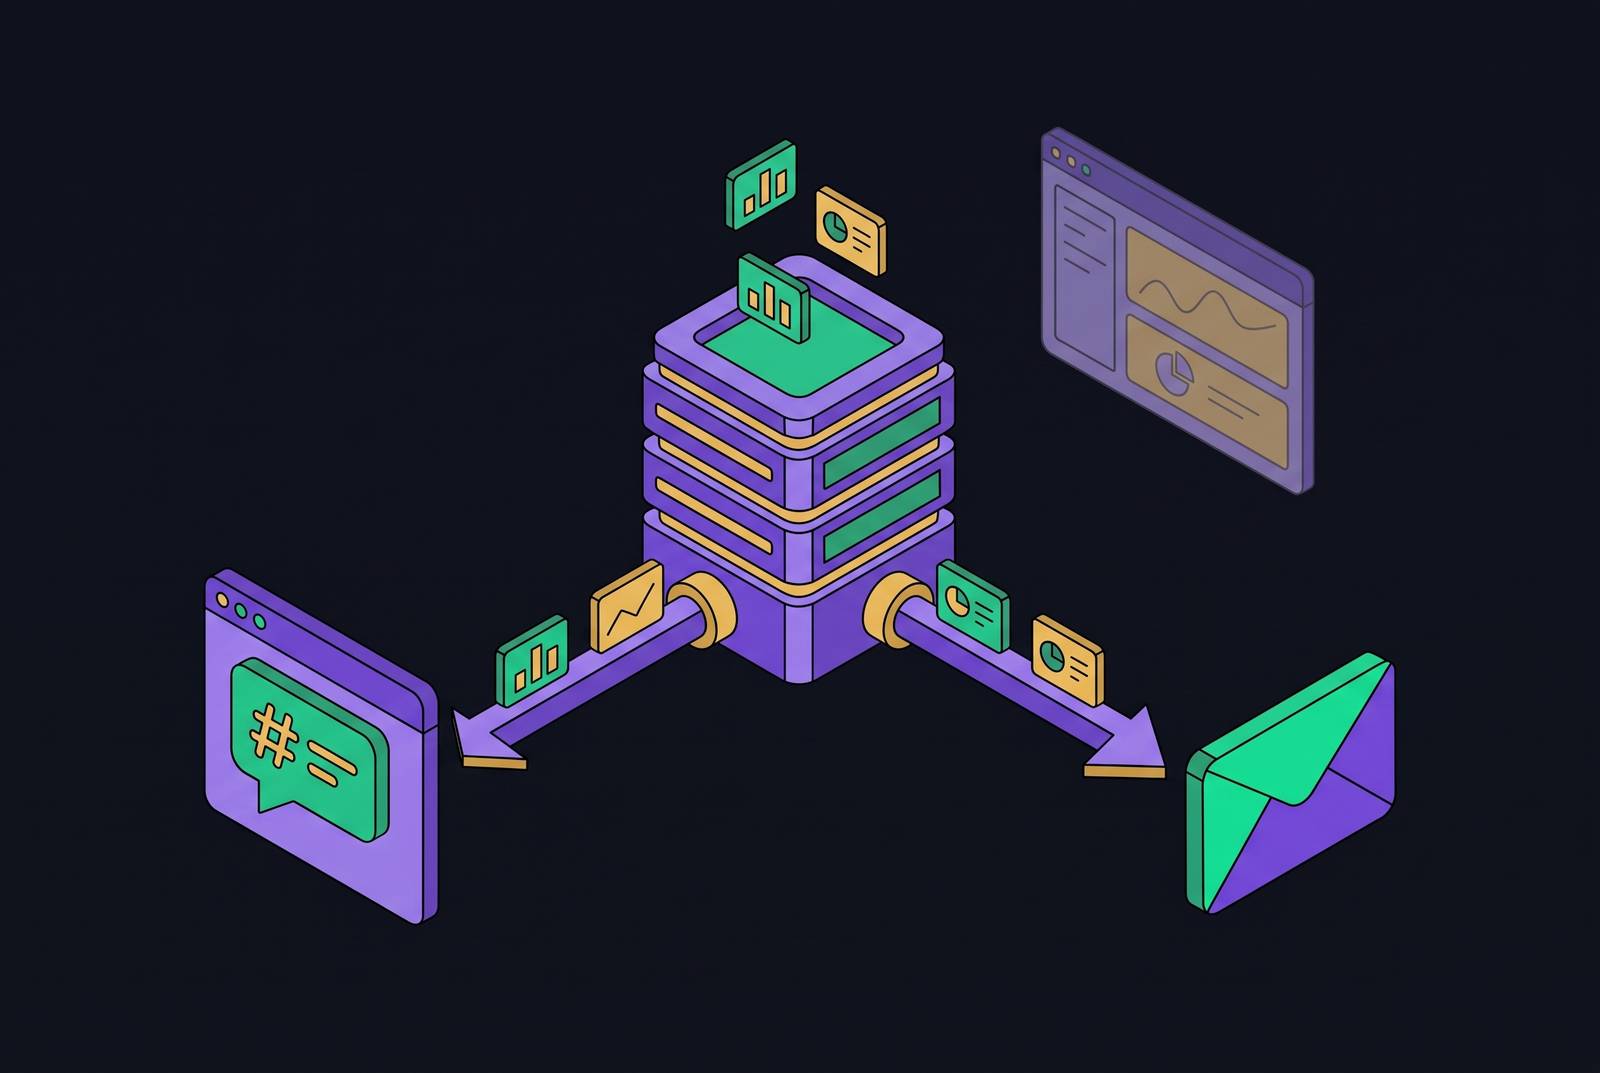
For Supabase SaaS teams, reliable metrics delivery to Slack and email starts with a single metric definition layer. Define MRR, churn, activation, and conversion rate once, pre-calculate their governed values, and serve them to every consumer through the same layer. Scheduled delivery then puts those numbers where people make decisions together, so each person no longer has to remember to find them.
Why dashboards fail as a team's operational center of gravity
Two people quote different “revenue” numbers in the same meeting. Finance has pulled one from its dashboard, while sales has brought another from its channel. The immediate problem appears to be a disagreement about the number, but the structural problem is that each surface computes it independently. With different filters and inclusion rules, the same business measure has several definitions that disagree. Reconciling them becomes recurring work because resolving today’s discrepancy does not remove the separate expressions that produced it.
The problem deepens when metric logic belongs to a chart configuration. If the definition of “active customer” is trapped inside one interface, a new consumer must reimplement it. An embedded app, Slack bot, or AI agent then adds another place where the definition can drift. The dashboard may calculate its own expression correctly even as people in the organization stop agreeing on what it should mean.
Even a dashboard with sound definitions remains a pull mechanism. Someone must remember to open it, find the relevant view, and interpret the result away from the conversation where a decision is forming. Relying on each person’s habit works especially poorly under pressure, when people need to make decisions quickly. Dashboards remain useful for analysis, but using them as the primary delivery mechanism makes shared awareness depend on separate acts of attention.
How can Supabase teams define metrics once and reuse them everywhere?
Headless BI moves metric logic out of the presentation layer and into a governed metrics layer that every consumer reads. That layer holds the metric definitions, dimension relationships, and logic that works out each measure. An API exposes those definitions and values to dashboards, Slack bots, email digests, and AI agents. The dashboard becomes one consumer among several rather than the place where the business’s meaning is stored.
A dashboard with an API can still keep its logic tied to chart configurations and return only chart data. A complete headless BI implementation instead includes a metrics and semantic layer, access control, and caching. The semantic layer is the governed model of the business that gets built. Headless BI is how that model reaches the different presentation surfaces through interfaces.
MRR makes the difference concrete. When finance decides that MRR should exclude one-time setup fees, the expression changes in the shared layer. Every dashboard, scheduled message, and agent that reads that definition then uses the same rule. The same principle applies when analysts and other teams calculate conversion rate differently in Supabase.
Why Slack and email are where operational decisions actually happen
For most teams, Slack and email are where people discuss changes, assign attention, and act. A scheduled summary places the number in that workflow without requiring someone to retrieve and redistribute it. The report becomes a shared artifact rather than the result of one person remembering to check.
Cadence matters because awareness and interruption serve different purposes. A weekly digest establishes a baseline for discussion, while a threshold alert calls attention to a change that cannot wait for the next report. Matomo’s Slack integration sends reports to match those rhythms, with campaign reports for marketing every Monday, weekly adoption metrics for product, and daily conversion tracking for sales. Stakeholders can also get the metrics they need without being given broad access to the analytics system.
Slack is a notification layer, and an email summary cannot perform root-cause analysis. People still need the source platform to look into the details and manage subscribers or campaigns. Replacing the dashboard as the operational hub therefore does not require eliminating it as an analytical tool.
What a governed, pre-calculated metric looks like before it is delivered
Before a metric can travel safely across those surfaces, its definition must be canonical. That means one expression, one set of inclusion and exclusion rules, and one owner. Pre-calculation adds a separate guarantee about the delivery path by separating computation from the moment a message is due. The scheduled process retrieves a value that is already prepared rather than asking each consumer to recompute it with potentially different filters.
For Supabase teams, the location of that computation matters as much as the definition. Postgres is row-oriented and tuned for transactional work, so analytical aggregations compete with live traffic for CPU and memory. Supabase’s documentation recommends a read replica for complex analytical queries to reduce load on the primary. A recurring push schedule pointed directly at production makes the competing workload regular.
A columnar layer above Postgres provides a place to pre-aggregate governed metrics without querying the production database at delivery time. Dreambase implements this pattern with governed Parquet datasets queryable through DuckDB, with metric definitions decoupled from the UI and exposed through an API and MCP server. Slack bots, email digests, dashboards, and agents can consume that shared layer without separate metric implementations. Its Supabase approach does not require ETL, schema changes, or a separate data warehouse. The important criterion is the separation between production transactions, governed computation, and the surfaces that display the result.
How scheduled delivery works from the metrics layer to the channel
The delivery path has three distinct stages, which are a schedule or trigger, retrieval from the governed metrics layer, and formatted delivery to the destination. A cron-style trigger starts the scheduled path on a daily, weekly, or monthly cadence. It retrieves the pre-calculated metric, formats it for the channel or inbox, and posts it. No dashboard needs to be opened, and no person needs to assemble the report.
Alerts use the same governed source but a different trigger. A threshold or anomaly check runs continuously or at a short interval and sends a notification when a defined rule or learned baseline is crossed. Go Insights for Slack illustrates how the two modes work together. Its weekly summaries for each account arrive every Monday at 8:00 AM with key metrics and week-over-week changes. Between reports, a meaningful deviation can trigger a mid-week anomaly alert, such as a spend-over-pace warning for a specific client.
Routing completes the mechanism by matching the message to the people who can act on it. A conversion alert goes to marketing, an MRR digest goes to founders and finance stakeholders, and a churn signal goes to customer success. The remaining constraint is freshness, because a message cannot be more current than the data behind it. A batch refresh may suit a weekly digest, while an urgent alert requires a faster refresh cadence or a streaming source.
What a team's metric cadence looks like without a dashboard as the hub
On Monday morning, MRR, weekly active users, and conversion rate arrive before standup in the Slack channels where teams need them. The team’s first conversation begins from numbers already delivered to everyone who needs them. Nobody has to pull a report or share a dashboard screen to establish the starting point. For a founder or operator, that changes the meeting’s preparation from report assembly to interpretation.
When CAC spikes or conversion rate drops below a defined range, the relevant channel receives the magnitude of the change and the likely affected segment. Attention follows the signal rather than the chance that someone was watching a chart. That rhythm can change as the team moves from pre-PMF to post-PMF, because the metrics and delivery cadence should follow the decisions the team needs to make. As those needs change, the metrics still come from the shared definition layer.
Reports for the board and investors can use the same source without having to calculate the numbers again. A weekly or monthly email digest arrives in the founder’s inbox formatted for forwarding, using the governed values prepared for delivery. This saves someone from having to copy numbers from different tools into another report. For a solo founder or a small team managing multiple accounts or products, automated aggregation replaces hours of reporting work. The gain is time for analysis.
Why AI agents make a governed push layer non-negotiable rather than nice to have
An agent with production database credentials, no query controls, and no oversight can generate damaging load at machine speed. A misconfigured query can degrade the production system for real users. The same separation that protects people from definition drift therefore also protects the transactional database from uncontrolled analytical access.
To keep access safe, agents get read-only access to pre-modeled datasets outside production, and the data layer enforces the access controls. That boundary matters when agents construct SQL dynamically, because application-level review cannot practically test every generated query for safety and correctness. Identity-aware controls at the data layer govern access where the data is served.
MCP, or Model Context Protocol, standardizes how an agent connects to a data source, but it does not establish whether the returned metric has the right definition. That responsibility remains with the governed semantic layer behind the server. In an implementation such as Dreambase’s, the MCP server exposes the same pre-modeled datasets used for human reporting. For Supabase teams building with AI agents, governed access therefore needs to be built in now instead of waiting for a future upgrade to reporting.
How to set up push delivery from a Postgres-native metrics layer for a Supabase team
The setup begins with definitions, before any delivery mechanism is built. For each metric, establish what counts, what is excluded, and which timestamp governs the reporting period. Record that definition in a shared layer. This applies equally to MRR, churn, activation, and conversion rate.
The second step is to move analytical computation away from the primary Supabase instance. A columnar representation such as Parquet datasets provides a purpose-built analytical path, while a read replica is another way to separate complex queries from primary traffic. A recurring query against the primary database should not become the foundation of the reporting schedule.
The third step is to configure schedules, routing, and alert conditions against the governed layer. A weekly MRR digest can go to the #revenue channel, daily conversion rate can go to the growth team, and a CAC threshold alert can go to the founder. The fourth step is to expose that same layer to agents through MCP with the same access controls. This extends the existing metric source rather than building another one, and it does not require granting agents writes or uncontrolled reads against production.
For Supabase builders without a data team, Dreambase handles the second through fourth steps as a managed layer, combining Parquet datasets, DuckDB queries, scheduled delivery, and MCP access without new infrastructure to manage. Teams building the pattern themselves still need the same separation of responsibilities. Neither route removes the first task, and forwarding dashboard output does not substitute for it. Start with the metric whose definitions already lead people to disagree, agree on its rules, and put that expression in the shared layer before setting a schedule to deliver it.