Decoupling Metric Calculation From Visualization Tools
Defining metrics once lets dashboards, agents, and bots agree.
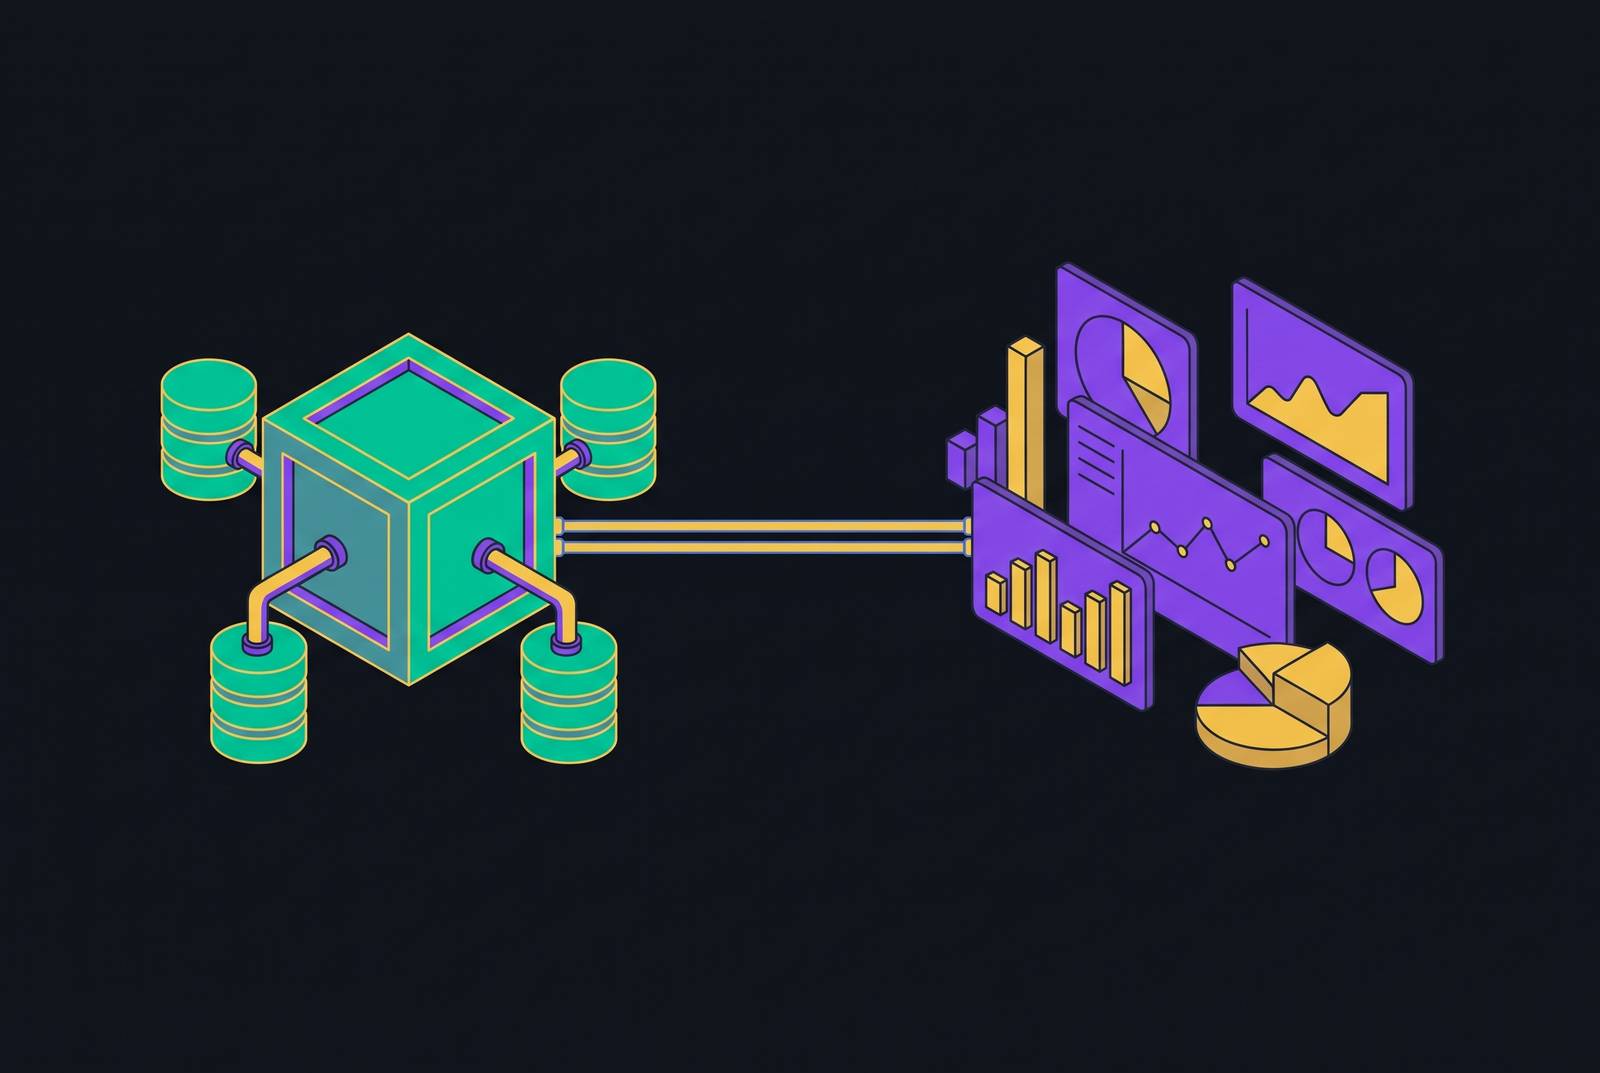
Decoupling metric calculation from visualization tools gives Supabase SaaS teams a single metric definition layer that survives front-end changes. For teams that need API control without a required dashboard UI, the architectural fit is headless analytics backed by governed, pre-modeled datasets. Dashboards, AI agents, and Slack reports then use the same calculated metrics without having to rebuild business logic or query production tables for every request.
Why metric logic ends up trapped inside visualization tools
A finance dashboard, a sales Slack report, and a product metric can all report slightly different versions of revenue. One calculation uses the order date, another uses the ship date, and a third handles trials in a different way. Each surface may look internally consistent while disagreeing with the others. The structural cause is that calculation and presentation were built together, so each surface owns its own interpretation of the business.
That ownership becomes a trap when an analyst defines “active customer” as a calculated field inside a dashboard tool. If the definition has no API or exportable contract, another application cannot reuse it. The next report must reconstruct the calculation from raw tables. Reconciliation is not an occasional error correction in this architecture, but a recurring consequence of where the definitions live.
Three compounding costs that follow from metric logic living inside the UI
The first cost is definition drift. Each reimplementation has its own maintenance path, so a new exclusion rule or date field must be changed in every copy. If an update is missed, a report can keep working as usual but give a different number. The resulting disagreement consumes analytical effort that should have gone toward explaining business performance.
The second cost is vendor lock-in. When business definitions exist only in a proprietary tool format, replacing the visualization layer also means rebuilding the measurement system. Drift makes that migration harder because the team must first decide which version of each metric is authoritative. A front-end choice has become a dependency for the business logic beneath it.
The third cost is new consumer exclusion. An embedded product widget, Slack bot, or AI agent can reuse a definition only if it can reach it. Reimplementation gives that consumer an answer, but it also adds another copy to maintain. AI agents make this problem particularly acute because they are becoming first-class consumers of business metrics without access to definitions trapped in BI formats. Together, the three costs form a feedback loop in which exclusion produces more copies, drift complicates migration, and lock-in preserves the architecture that caused both.
How do you decouple metric calculation from the dashboard UI?
Decoupling puts definitions in a shared layer that every surface can query. For example, monthly_recurring_revenue is defined once for all destinations. The executive dashboard, customer-facing app, AI assistant, Slack bot, and reverse-ETL job to the CRM all read from that definition. There are five surfaces, but only one formula and one update point. Replacing the dashboard no longer requires replacing the meaning of MRR.
The semantic layer describes what the shared model means for the business, while headless BI describes how applications use it without depending on a visualization tool. The model contains entities such as Customer, Order, and Subscription, together with their relationships. It also has calculation logic, time rules such as YTD or rolling 28-day periods, and governance policies such as row-level security and column masking. Natural-language synonyms can make those definitions accessible through LLM interfaces without giving the LLM responsibility for inventing them.
This changes the dashboard’s role from author of business logic to consumer of it. A standard interface, whether an API, query protocol, or MCP server, becomes the route to the authoritative definition. Reports, embedded products, and automated workflows can all use the same contract. To pass this test, the architecture must let a new consumer get MRR without writing its own MRR calculation.
Why pre-calculating metrics into governed datasets goes further than serving them on demand
A shared definition solves duplication, but it does not necessarily remove repeated computation. A semantic layer that compiles queries on demand still calculates results when a dashboard loads, an agent asks a question, or a Slack report runs. When those queries run against the source database, the production system still has to do the work of answering them. Centralizing the formula and separating the workload are therefore distinct architectural decisions.
Pre-calculation helps with the second decision by doing expensive aggregation before the results are needed. Materialized views are a first step in Postgres because they store calculated results rather than repeat complex aggregations for every request. Supabase teams that move expensive reporting workloads to materialized views or external analytics systems before they scale are less likely to have to make that move under pressure. However, materialization alone is not the same as isolating analytical reads from the transactional primary.
Governed Parquet datasets queryable through DuckDB extend the pattern by placing modeled metrics in a format suited to analytical reads. Dreambase implements this approach with pre-modeled metrics in governed Parquet, queryable by DuckDB and served through a single MCP server, so consumers do not reach the production Postgres instance. Dashboards, agents, and reports read the same pre-computed artifact rather than independently recalculate its metric logic. A versioned artifact also preserves what a metric meant at a particular point, supporting audits, reconciliation, and investigation of agent outputs. The advantage is both operational and interpretive, because the result has a governed calculation behind it and a history that can be examined.
How AI agents change the stakes for metric governance
AI agents bring weaknesses in metric governance to light faster than human users because they work at machine speed and scale. An agent generating SQL against a production schema can misread relationships, produce a hallucinated query, or request data beyond what its task requires. Even when a semantic layer helps it build SQL, the query can still interfere with production if it runs against the primary database.
MCP provides a standard way for AI applications to connect to external tools and data sources. Anthropic introduced MCP in November 2024 and donated it to the Agentic AI Foundation under the Linux Foundation in December 2025. Its enterprise-facing roadmap includes audit trails, SSO auth, and gateway patterns. Those concerns matter because a reachable dataset is not automatically a properly controlled dataset. Standard connectivity makes the quality of permissions, naming, and metric definitions more consequential.
The recommended boundary is a metrics-layer API or pre-calculated dataset, with no production database credentials held by the agent. Agent access should pass through a gateway that enforces permissions and logs access. For Supabase teams using Dreambase’s MCP server, the analytical surface is pre-modeled Parquet queried through DuckDB, leaving production Postgres structurally outside agent queries. This headless pattern also lets an agent consume the same business context as a dashboard without requiring a prebuilt dashboard UI.
What a governed metrics layer needs to actually deliver on the promise
A decoupled layer must satisfy four conditions to resolve drift, lock-in, and exclusion. The first is centralized, version-controlled definitions. If MRR changes to exclude setup fees, every consumer must receive that change through the shared definition. The previous definition must remain auditable. An agreed data dictionary gives terms such as “Churn” and “Active User” a stable meaning that the machine-readable model can enforce.
The second condition is that the same access control rules apply to every consumer. Row-level security, column masking, and object-level permissions belong at the metrics layer, so dashboard and agent rules do not have to be kept up to date separately. Otherwise, a governed calculation can still expose data through an ungoverned edge. For agents, this calls for least-privilege service accounts and gateway-mediated access.
The third condition is general-purpose reachability through standard interfaces, including SQL, REST, GraphQL, or MCP. Each required consumer must be able to use the layer without reimplementing its business logic. The fourth condition is analytical compute separated from the production transactional path. Materialized views can reduce repeated calculation, while read replicas or pre-computed Parquet datasets can support a separate analytical read path.
These criteria distinguish a reusable metrics backend from another application that happens to contain metrics. They also give Supabase teams a way to assess infrastructure before connection limits and chatty queries become production constraints. As one implementation addressing all four conditions, Dreambase combines governed, pre-modeled Parquet datasets, DuckDB analytical reads, and a single MCP server without requiring a separate data warehouse, ETL pipelines, or schema changes. It extends the existing Postgres project. The evaluation remains the same for any approach, namely whether definitions, permissions, interfaces, and compute boundaries remain consistent across consumers.
Applying the decoupled layer to the metrics a startup actually tracks
For an early-stage SaaS team, governance matters most for the small set of numbers used repeatedly to make decisions. The core set is MRR, CAC, LTV, churn rate, and cash runway, with other metrics feeding or explaining the North Star number. Activation rate and product usage can help explain how the business is doing without becoming separate versions of its financial measures. Tracking more than five to ten carefully chosen metrics spreads attention thin and may not lead to better decisions. The layer’s value is consistency across the core measures.
Each metric on a CEO dashboard should reconcile to an authoritative source. ARR comes from billing, cash comes from the bank, and product usage comes from a governed analytics layer. When the North Star Metric is defined once, the founder’s dashboard, investor update, and agent’s weekly summary can all report the same number. That removes a reconciliation step without removing the need to interpret what the number means.
An agent preparing board reports or flagging anomalies will use whichever numbers it can reach. If those numbers are independently calculated from raw tables, the agent inherits their inconsistencies. A governed, timestamped artifact instead makes it possible to identify the data behind the agent’s output when a human reviews it. Once that foundation exists, delivery can move beyond waiting for someone to open a dashboard. Pre-calculated metrics can arrive in an inbox, Slack message, or daily digest, so trusted numbers become part of the workflow without anyone having to ask for them.
Why founding teams should treat the metrics layer as infrastructure, not a later-stage concern
Deferring proper analytics leaves business definitions to accumulate inside dashboards, reports, and agent workflows. Each additional consumer increases the work required to identify authoritative calculations and unwind divergent copies later. Establishing the shared layer at founding is cheaper than correcting a measurement system after its inconsistencies have become dependencies. For a pre-PMF team, the relevant cost includes engineering time diverted from product iteration to pipeline maintenance.
Supabase teams also need visibility into whether analytical workloads are already affecting production. Query latency, connection counts, and slow-query patterns show where the system is under strain in ways that the amount of raw data alone cannot explain. Supabase’s Metrics API exposes Postgres performance and health metrics in Prometheus exposition format. Signals to watch include how close active connections are to max, Realtime channel metrics, and CPU/memory pressure. Observability from day one helps teams separate the analytical read path before connection limits or slow queries force them to make a change in a hurry.
Early infrastructure need not mean building a dedicated data function. A governed layer that extends the existing Postgres project can provide reusable metrics and a safe agent surface without ETL, schema changes, or new infrastructure for the founding team to manage. A founder can then work from one governed number that both the team and its AI agents trust, without a data engineer on payroll.