Analytics Infrastructure Decisions That Supabase Teams Get Wrong Before They Need an API
Early schema and access choices decide whether analytics hold up.
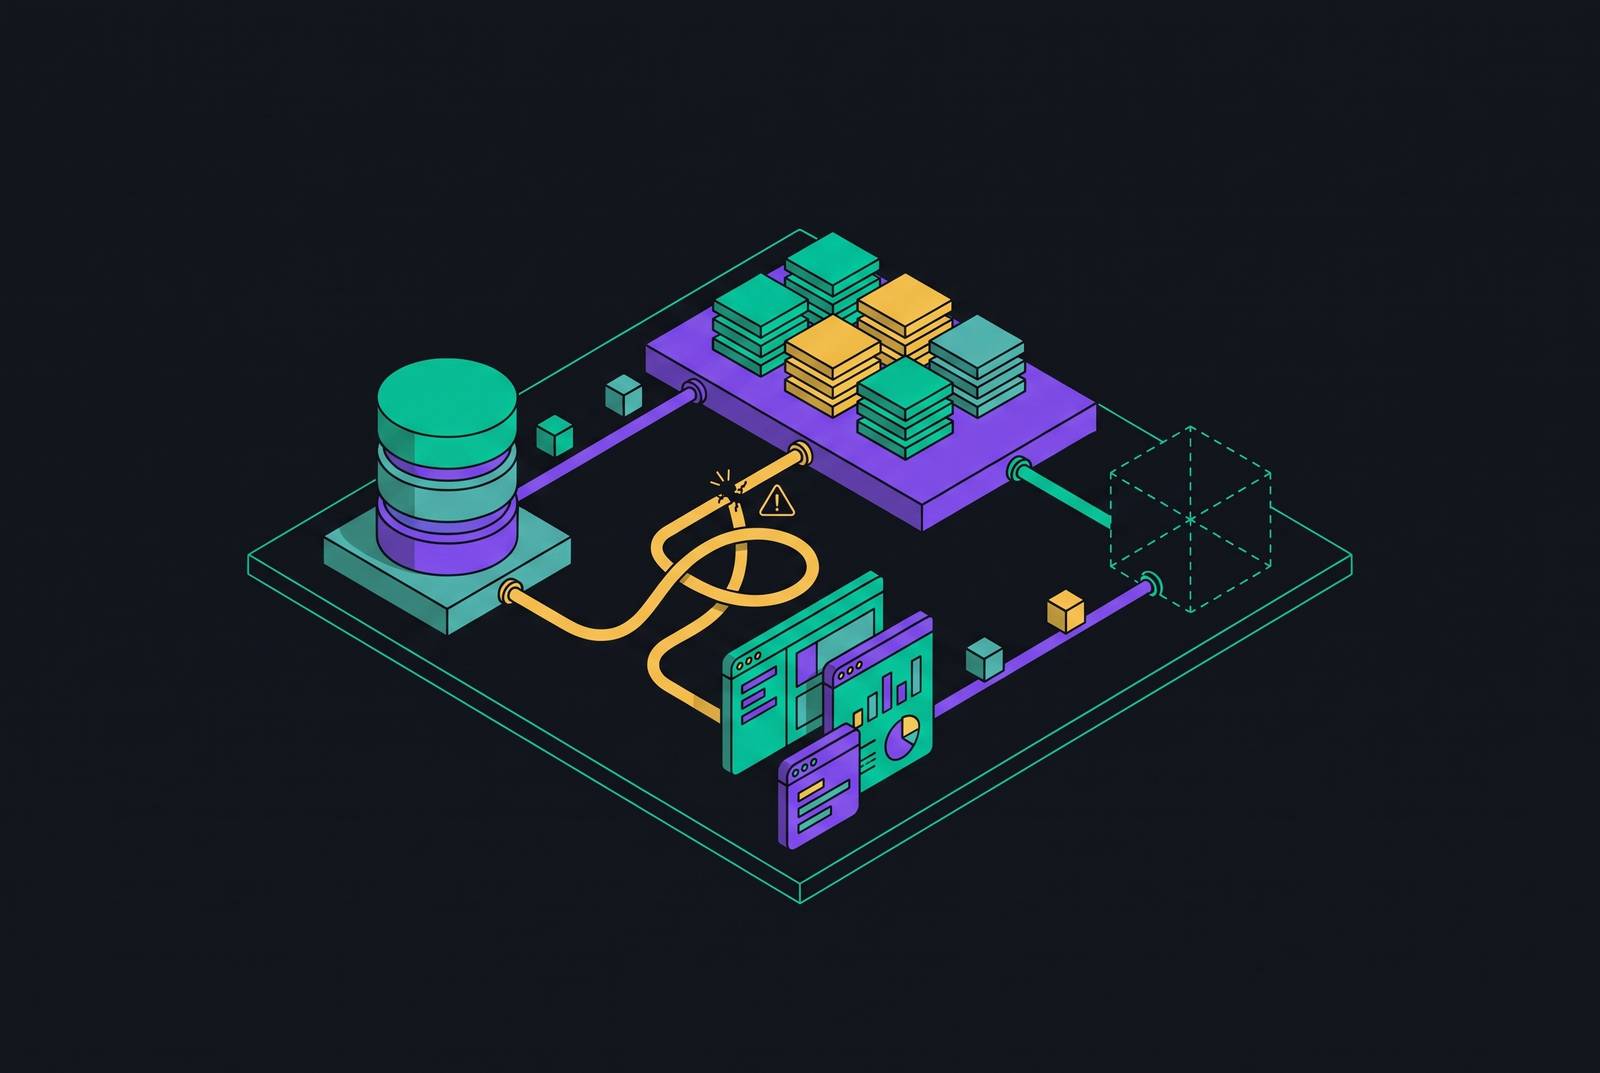
For Supabase teams, a headless analytics platform for API-first and agent-first access needs typed data, separate analytical workloads, and shared metric definitions. Trustworthy usage analytics depend on those foundations more than on the API that exposes them. The decisive infrastructure choices happen before the first API call, when teams establish Postgres as an analytical home or limit it to an operational backend.
Why so many Supabase projects hit an analytics wall they did not see coming
Supabase lets teams ship a working backend quickly, while the analytical cost of early schema choices remains largely invisible. An application can work well for months without showing that its records can support a KPI report people can trust. The gap becomes visible when a dashboard or an agent context window needs a consistent calculation across records that were modeled only for individual product interactions.
At that point, a BI layer, a warehouse, or an ETL pipeline can seem to solve the problem. But none of those choices settles what an inconsistently modeled field means or which records belong in a metric. Postgres can serve as a genuine analytical home, provided the data model supports that role rather than merely accommodating the next application request.
What JSONB overuse actually forecloses at the analytics layer
JSONB is attractive when product requirements change quickly and frontend engineers want to ship without schema migrations. It gives fields a place to go while their shape is still being worked out. When business-critical state moves into an unconstrained document, every later calculation must recover the structure that the schema did not establish. Billing data, tenant permissions, workflow events, and feature flags then need to be interpreted each time they are used, though they should be stable inputs.
Preferences can be genuinely optional or sparse, so JSONB can fit their role without defining the meaning of a business metric. Raw webhook payloads can belong there for the same reason. Core billing state needs fields with types and meanings that stay the same because calculations rely on them. Tenant permissions likewise need an explicit structure.
Six months after launch, an undocumented JSONB column can leave a team uncertain about which fields exist and how to query them safely. Indexing does not settle that uncertainty by itself. A simple whole-column B-tree index does not help analytical queries that pull out individual keys, though GIN indexes and B-tree expression indexes on extracted keys are supported. Nor does the JSONB type alone validate the business structure inside the document.
The decision rule is to give stable, queryable fields typed columns and constraints, while reserving JSONB for truly semi-structured metadata. A GIN index belongs on that metadata only where access patterns justify it. Ad-hoc casting is not an equivalent substitute for modeling. Different engineers can cast the same stored fields differently and produce different numbers from the same records. The analytical loss is therefore not simply inconvenient SQL, but a shared definition of the inputs to a calculation.
How missing indexes become an analytics problem, not just a performance one
Queries that feel fast at a few thousand rows provide little pressure to plan indexes. By hundreds of thousands of rows, the delayed cost can appear in dashboards and reports as well as application list pages. This changes the nature of the failure. When precise aggregation becomes too slow to use, teams begin avoiding the queries that would otherwise produce their authoritative numbers. A performance omission becomes a constraint on what the business can reliably measure.
The common workarounds introduce a second problem. Pre-pulling records into spreadsheets or caching stale snapshots moves reporting away from the query that defines the current result. Those copies may make a report available, but they also create opportunities for metric drift. A failed query is not itself a valid number. A report loses trust when it shows an incomplete result or a stale substitute without making that limit clear, so a figure can look right while failing to answer the question asked.
Teams should plan indexes when they do data modeling as well as when they handle incidents. Composite indexes should reflect the common WHERE, JOIN, and ORDER BY patterns used by dashboards and reports. EXPLAIN ANALYZE provides the diagnostic tool at each major product workflow change. The objective is to keep precise queries usable so that reporting does not depend on progressively less reliable substitutes.
Why Row Level Security written for users does not protect analytics queries or agent access
Row-level access policies built for human sessions do not by themselves make analytical access safe. A rule based on auth.uid() applies to a particular user context, while a service-role reporting connection takes a different path to the data. The distinction is structural. Enabling the feature does not establish that every consumer reaches the tables with the identity and permissions the policies expect. An agent reading those tables exposes the same unresolved boundary.
Broad policies such as “authenticated users can read everything” leave that boundary especially weak. More narrowly scoped user policies still do not constrain a service role that bypasses RLS. A reporting query under that role can include rows the querying user should never see. A tenant-specific number that includes unauthorized rows is wrong even if the arithmetic is right, because it measures the wrong population.
The policy model for the application should use ownership and team membership rules with clear conditions, including user_id = auth.uid() and organization membership joins. Writing down those rules for each table makes them available for audit. Analytical access needs a separate decision at the data layer. Rather than accumulating RLS exceptions, teams should keep analytics queries away from the production instance with production permissions. Agent access belongs within that analytical model.
What separating operational and analytical workloads actually means for a Supabase project
Heavy aggregation queries compete with transactional queries for connection pool slots when both run against the same Postgres instance. On Supabase, connection pool exhaustion is a production failure mode. Long-running reports and event-volume queries are therefore not merely additional endpoints on an otherwise unchanged backend. The architecture must keep their workload separate because of how they access data.
Supabase can remain the product backend for auth, storage, transactional operations, and operational queries. Analytical traffic can then use a separate data path for heavy aggregations and reporting. A custom API does not create isolation if it forwards every analytical request to the same production tables. For teams seeking raw API access without a prebuilt dashboard UI, the decisive criterion is where the API obtains its results and which workload pays for calculating them.
Agents make that criterion more urgent because direct queries against production Postgres can exhaust the same connection pool. Adding MCP server instances lets the access layer handle more requests, but the database is still a bottleneck. Protocol capacity is not database capacity. The stateless MCP revision finalized on July 28, 2026, makes the access layer easier to scale behind a load balancer, but does not remove the need for data-layer separation. More routes to production do not provide an independent place to perform analytical work.
Materialized views are an option for simpler aggregations, while heavier traffic or agent access calls for a governed analytical copy. These choices should not be treated as interchangeable. Precomputing a simpler aggregation saves doing the calculation again, while moving heavy analytical traffic off production also deals with contention and the access boundary. The architecture must make clear which problem it solves before an analytics feature depends on it.
Why pre-calculated metrics prevent the drift that schema fixes alone cannot stop
Even with a well-modeled schema, business numbers can disagree. One engineer can calculate SUM(revenue) and another SUM(amount_captured), even when the records both read are correct. Typed columns make the inputs more dependable, and indexes make the queries usable, but neither chooses the calculation. Metric drift persists until that choice becomes a shared rule.
Agents add another consumer capable of interpreting the same tables differently. Direct table access asks the agent to construct a definition as well as retrieve data. That is a separate responsibility from answering a question. As more people and automated consumers write their own queries, there are more chances for their results to disagree. A shared semantic layer constrains the meaning of a metric before any particular interface requests it.
That layer defines complex calculations such as MRR, LTV, and churn in one central place. Updating a calculation once can then propagate the definition to every consumer. A dashboard alone cannot provide that guarantee. Its calculation governs only the consumers that actually use it, leaving other APIs or agents free to choose another interpretation. The required control belongs beneath those interfaces, where it can govern the datasets they all receive.
Pre-calculated datasets store the results of those definitions and keep them governed, so consumers can query them without hitting production. They are the appropriate unit for human dashboards and agent context windows because the calculation remains durable and auditable. This gives API control a dependable foundation. A team can choose its own frontend, or provide usage analytics to an agent without a dashboard UI, while retaining a common definition of the reported numbers.
For Supabase teams without a dedicated data function, the safe pattern is a governed analytical copy behind a protocol layer such as an MCP server. Agents discover available datasets by name rather than constructing ad-hoc queries against production tables. The protocol exposes governed results. This pattern keeps agent query traffic away from the operational workload while enforcing the semantic layer for every consumer. It joins the workload boundary to the metric definition instead of treating security, performance, and correctness as unrelated concerns.
The decisions to make before the first API call, in the order they matter
The first decision is schema shape, before a prototype ships. Teams should choose which fields need to stay stable, typed, and queryable, then give those fields columns and constraints. JSONB should remain available for genuinely optional or structurally unpredictable metadata. This establishes the inputs that later calculations can trust. Without that distinction, index planning and metric definitions inherit uncertainty about the records they are supposed to serve.
The second decision is the index plan. Common dashboard and report patterns involving WHERE, JOIN, and ORDER BY should inform composite indexes created with the initial schema. The third decision is the access model. Ownership and team membership need explicit RLS conditions, with the tenant boundary documented table by table. At this stage, teams should also decide how analytics and agents will reach data, rather than assuming a human session or a service role against production will suffice.
The fourth decision is the workload boundary, before the first analytics feature ships. Simpler aggregations can use materialized views, while heavier traffic and agent access need a governed analytical copy. The fifth decision fixes the business meaning of results. Teams should name the five or fewer KPIs they will be held accountable to, write their definitions once, and enforce them at the data layer.
Deferring these choices shifts the work into data cleanup, schema migrations, and trust recovery. It does not remove the work from the product. Supabase provides the primitives, and Postgres has the capability, to support a genuine analytical home. Achieving that outcome depends on treating schema, access, workload separation, and metric definitions as product decisions before the first API call.